Evaluating AI Financial Spreading Platforms Against the Demands of Institutional CRE Underwriting Workflows
Institutional lenders should evaluate spreading platforms on source traceability and workflow fit.
Purpose-built CRE financial spreading platforms can automate rent roll and operating statement extraction, populate underwriting models, and support credit memo preparation. Institutional buyers should evaluate them on document reconciliation, normalization, source traceability, and analyst review. The right platform supports the full underwriting workflow without obscuring how a figure became a conclusion.
Why document extraction is not the same as institutional underwriting support
The surface workflow appears straightforward enough to automate. Spread the operating statement, calculate NOI, size the debt, and check DSCR, debt yield, and LTV. The harder work comes between those steps, when an analyst checks whether the documents support one another. A rent roll must support the reported operating income, lease terms must reconcile with that income, and the T-12 period must be checked against the appraisal’s effective date.
Genuine AI extraction also differs from scripted automation. Scripted tools working on structured data break on irregular formatting, handwritten tables, and scanned financials that purpose-built NLP and computer vision can handle. Yet handling those inputs is only the beginning. The strongest workflow extracts structured fields, runs a completeness checklist, assembles a scored record for analyst review, and routes conflicts and gaps to a named human reviewer. The tool assembles inputs while the human owns every conclusion. Headline extraction accuracy therefore answers the wrong question.
What institutional deal standards actually require from a spreading platform
Institutional evaluation rests on four dimensions, which are document breadth, cross-document reconciliation, source fidelity, and audit-trail completeness. Document breadth means handling the package a deal actually produces, including OMs, T-12s, rent rolls, lease abstracts, tax returns, K-1 attachments, and personal financial statements. Yardi or RealPage exports and interim QuickBooks files belong in that assessment too. Clean GAAP statements alone are not a sufficient test.
A rent roll that does not reconcile to the T-12 should produce a visible conflict, as should a lease amendment that contradicts a reported concession. The same standard applies when an OM’s stated vacancy differs from what the rent roll supports. Independent extraction leaves that work with the analyst. A platform that claims underwriting support must therefore be assessed on the inconsistencies it identifies across documents and the fields it captures.
Source fidelity requires every extracted figure to reference its originating document, page, and line item. Audit-trail completeness addresses what happens after extraction. Seller figures, reviewer adjustments, and model assumptions must remain in separate fields with timestamps, preserving who changed what and when. Together, these requirements let an examiner trace a spread back to its evidence without leaving the platform. They also turn a pilot into a test of reviewability.
Where the platform market actually splits, and why the segmentation matters for buyers
The market divides by buyer seat and workflow. Commercial lender tools read borrower packages, spread multi-entity returns, build global cash flow, check credit policy, and draft a credit memo with citations. Their intended shift is from analyst construction to analyst review. AI credit decisioning, by contrast, mostly addresses consumer credit scoring and approve-or-decline automation. Treating that category as interchangeable with commercial financial spreading risks buying a tool for a different problem.
Acquisition-side document-to-model tools form another distinct segment. Their job is to populate existing Excel or Argus templates. These are data population tools and should be evaluated as such, including how faithfully they feed the buyer’s proprietary model. A lender needs a policy-aligned credit record, while an acquisition team needs usable inputs in the model that governs its investment analysis.
For a lender, even accurate extraction leaves questions about global cash flow and whether the memo agrees with it. For an acquisition team, it leaves questions about template mapping and re-keying. As agentic capabilities expand, this workflow distinction remains the basis for assessing what a platform automates and what the analyst must still complete.
How to evaluate platforms on the lender-side spreading and memo workflow
For CRE lenders, source-citation depth is a decisive criterion. Every figure in the output should link to its originating document and page, with enough detail to support the line-item standard established above. That documentation trail supports review only if a qualified analyst examines and approves the spread before it enters a credit decision. The vendor demonstration should therefore expose the route from the spread back to the underlying borrower document.
Multi-entity handling is the next test of institutional fit. Partnership returns, K-1 attachments, and operating entities introduce cash flows that must be consolidated. A platform limited to clean, single-entity statements does not meet that requirement, however accurately it extracts them. The output in the spread and credit memo must also agree. Generating both from the same underlying extraction reduces the reconciliation risk introduced when separate systems hand information to one another.
Tools that stop before close leave covenant monitoring to another workflow, while platforms that support it can reduce handoffs in ongoing portfolio management. Platforms strongest in granular source traceability tend to be weaker in narrative memo generation, while full-memo platforms often sacrifice traceability for narrative coherence. Before selecting, a credit team must decide whether its binding constraint is defensible source-level review or the work of assembling the memo.
How to automate rent roll and operating statement spreading into acquisition models
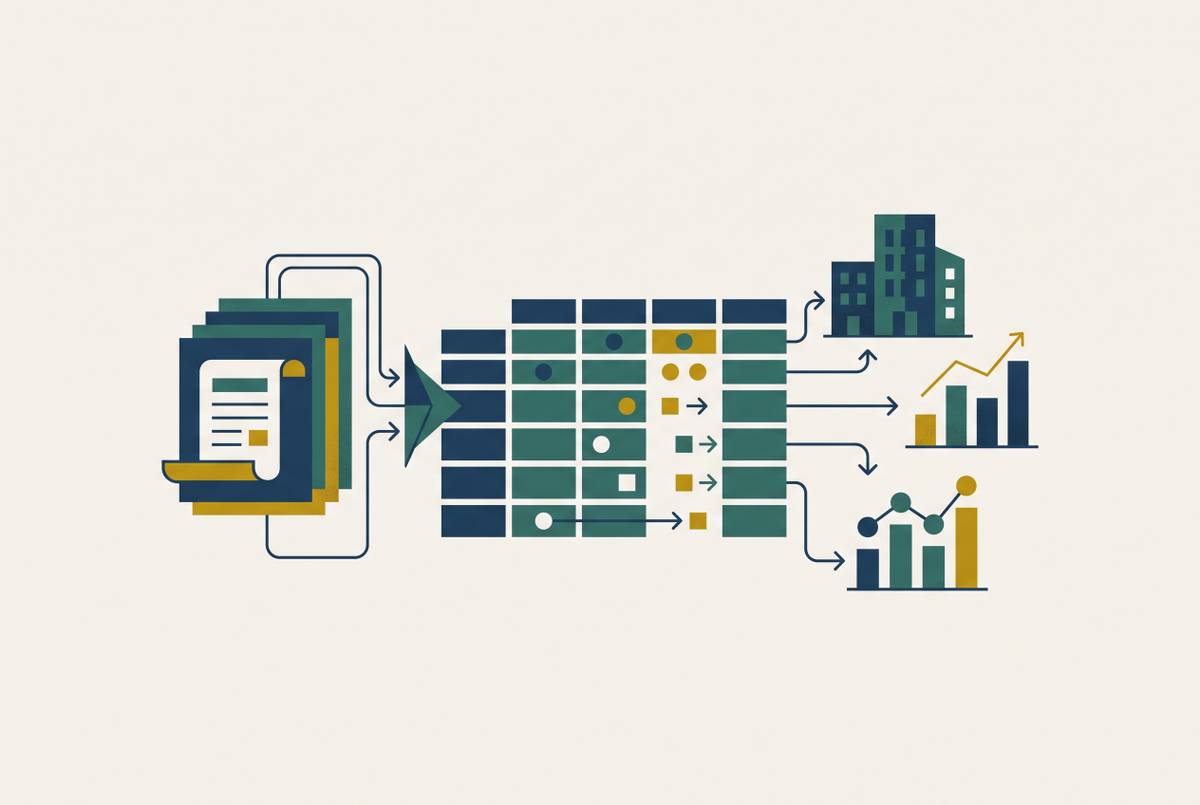
For acquisition teams and sponsors, model fidelity replaces memo completeness as the central output test. The platform must populate the firm’s proprietary Excel or Argus template without requiring analysts to re-key or reformat its output. This is the document-intake bottleneck. Converting an OM, rent roll, or T-12 into a populated model consumes analyst time before the investment analysis can proceed.
The integration layer therefore deserves as much scrutiny as extraction. A plugin that places output directly into an existing template can eliminate the manual entry step that otherwise erodes time savings. Requiring analysts to adopt the vendor’s model creates a different adoption burden, one that compounds over deal volume. Bring-your-own-model integration eases that burden by mapping the extracted output to the firm’s own model. Its value is practical, particularly where established Excel workflows shape how analysts work.
Multifamily-specific platforms can bring together rent-roll and T-12 parsing, comp pulling, and Excel workflow in ways that general document extraction tools do not. That breadth should still be judged against the buyer’s actual documents and destination model. Extraction quality alone is not the endpoint.
What agentic AI changes about the evaluation, and what it does not
Agentic AI links steps that sequential tools leave separate. A lender-authored workflow can chain OCR extraction, NLP analysis, risk scoring, decision recommendation, and rationale generation within one automated pipeline. In underwriting, that can mean ingesting borrower project files, spreading financials, calculating policy-defined ratios, and assembling the credit memo. The workflow can also extend into monitoring after close. This expands the scope of automation without changing the standard of evidence required for a credit decision.
The consequence is a larger error surface. At a manual handoff, an analyst has an opportunity to catch an extraction error before it enters the model. In an agentic pipeline, a misread rent concession or missing expense category can propagate through ratio calculations and into the memo before human review. More automation therefore makes source fidelity and conflict handling more consequential. A well-written narrative cannot make up for a wrong input that has passed through several automated steps.
The lesson for evaluation is to test uncertainty handling across the full chain. A demonstration should show whether low-confidence extractions reach a named reviewer rather than silently proceeding, and whether the audit trail remains navigable after the pipeline runs. The credit officer must still have the final say. Agentic lending remains early at most institutions, with board-level discussion more common than investment or deployment. Buyers should keep extraction-and-memo capabilities they have seen work separate from proposed agentic workflows that have yet to be shown in use.
The structural adoption barriers that evaluation frameworks tend to miss
When deal information sits in personal email folders, individual spreadsheets, and disconnected shared drives, a centralized platform can work only with the information it can reach. Even an accurate engine cannot reconcile documents it has not received. Institutional evaluation must account for whether the organization’s information environment can support the workflow being purchased.
The economics require an equally direct assessment. AI subscriptions, token usage, and implementation labor are operating costs that bring no benefit on their own. If that spending neither reduces other costs nor demonstrably improves deal throughput, the institution has added expense without an offset. Where those costs fall on assets under management, they have direct NOI consequences.
These constraints change what counts as a complete evaluation. A platform may pass document, reconciliation, and traceability tests even when the organization cannot give it the inputs it needs or justify what it costs to keep running. Organizational readiness belongs in the purchase decision for that reason. These barriers are addressable, and identifying them before selection is part of rigorous evaluation.
A practical evaluation protocol for institutional buyers selecting a platform
Purpose-built CRE platforms are the appropriate starting point for this evaluation, but the claim of specialization needs testing. Institutional buyers should run three anonymized deals through the platform, with a clean package, a scanned rent roll with irregular formatting, and a package with conflicting dates or missing expense categories. Each package tests a different weakness. Together, they distinguish performance on institutional documents from performance on a clean demonstration. The same deal set should support assessment of the buyer’s actual endpoint, whether a credit memo or a populated acquisition model.
For each extracted figure, the buyer should open the exact source page and line item. Missing values should be shown as unknown, while figures that conflict should go to a named reviewer. Seller figures, reviewer adjustments, and model assumptions should remain separate and traceable after the full workflow runs. Review effort needs measurement as well. Actual analyst correction time and review time on the pilot set provide the basis for assessing throughput gains.
CRE terminology provides a further test of normalization. GPR in a rent roll, Effective Gross Income in a T-12, and Gross Potential Rent or Gross Potential Income in an OM are related but distinct figures in the income waterfall. GPR/GPI represents income before deductions, while Effective Gross Income sits below it after vacancy, concessions, and bad debt. Those distinctions must survive the spread. Buyers should also test asset-class structures, including multifamily rent rolls, retail lease abstracts, and office operating statements, against their required workflow.
Finally, the pilot should establish whether the platform is genuinely unified. Extraction, spreading, memo generation, and covenant or portfolio monitoring on one data layer avoid the reconciliation errors that accumulate across disconnected point solutions. A suite of loosely connected tools should not receive the same assessment merely because it presents a common interface. The required endpoint may instead be an acquisition template or LP reporting output.